> For the complete documentation index, see [llms.txt](https://docs.cherryai.com.cn/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.cherryai.com.cn/docs/en-us/pre-basic/providers/cherryai/free-deepseek.md).
# DeepSeek V3.2
Cherry Studio users can now, via the built-in **CherryIN** service for free access **DeepSeek V3.2**— DeepSeek's flagship sparse-attention MoE model released on December 1, 2025, the first to natively integrate "thinking" into tool calling, making it an ideal choice for advanced agents and long-context scenarios.
***
## What is DeepSeek V3.2?
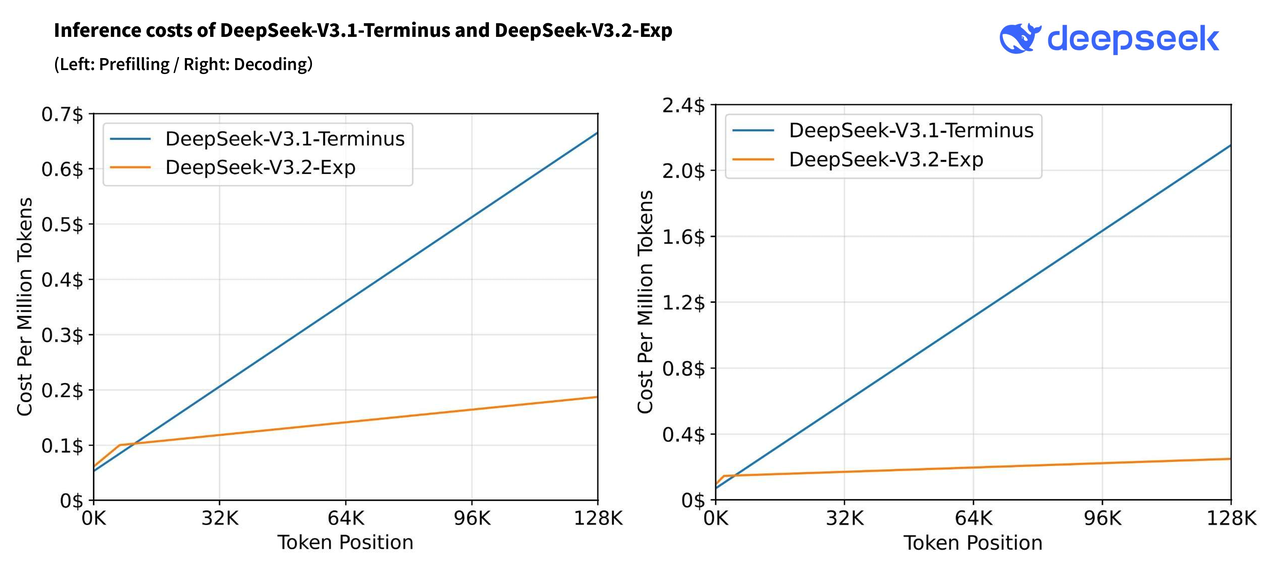
DeepSeek V3.2 evolves from V3.2-Exp, uses the Mixture-of-Experts (MoE) architecture, and introduces **DeepSeek Sparse Attention (DSA)** sparse attention mechanism, significantly reducing long-context inference costs while maintaining an ultra-large total parameter scale.
* Architecture: MoE + DeepSeek Sparse Attention (DSA) + Multi-Head Latent Attention (MLA)
* Total parameters: 685B
* Activated parameters per token: about 37B
* Number of experts: 256 experts per layer
* Open-source license: MIT
* Release date: December 1, 2025 (V3.2-Exp released on September 29, 2025)
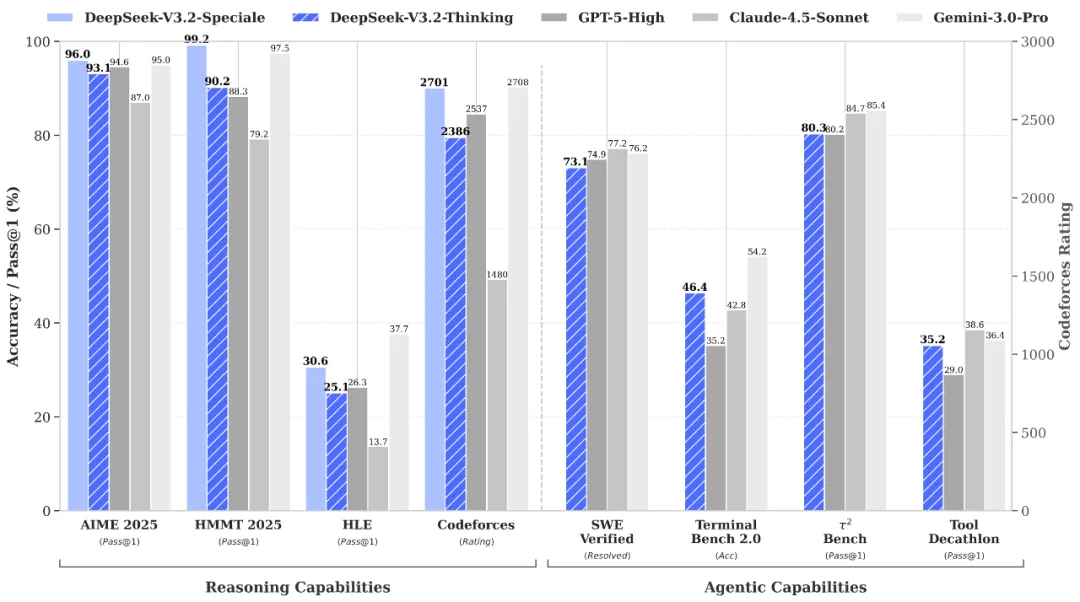
V3.2 also released an API-oriented **DeepSeek-V3.2-Speciale** version, achieving gold-medal-level performance in IMO, CMO, ICPC World Finals, and IOI 2025 on complex reasoning tasks.
***
## Continues a solid training and alignment pipeline
DeepSeek V3.2 inherits the mature training pipeline of the V3 series and makes key extensions for agent scenarios:
1. **Large-scale pretraining**: foundational training completed on massive, high-quality multilingual corpora covering code, math, and scientific knowledge.
2. **Introduction of sparse attention**: trained the main model and lightning indexer at 128K sequence length, with each query token selecting 2048 key-value tokens for attention.
3. **Large-scale agent data synthesis**: a new agent training data synthesis method covering 1,800+ environments and 85,000+ complex instructions.
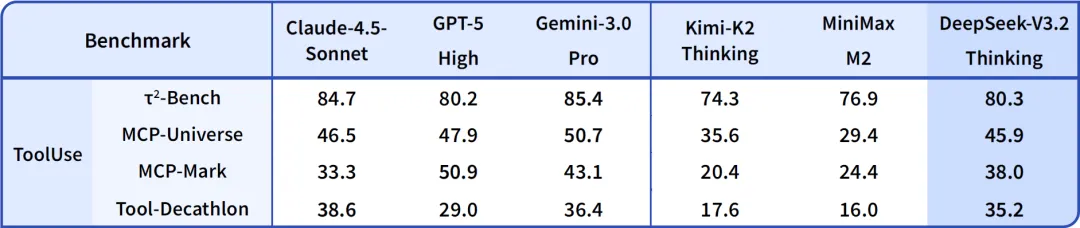
4. **Integration of thinking and tool calling**: V3.2 is DeepSeek's first model to natively integrate "thinking" into tool calling, supporting tool use in both "thinking mode" and "non-thinking mode".
***
## Flagship core capabilities
DeepSeek V3.2 focuses on comprehensive capabilities "on par with GPT-5" and is significantly enhanced in agents and complex reasoning:
* ✅ **Native thinking + tool calling**: The first DeepSeek model to integrate thinking into tool use
* ✅ **Top-tier reasoning ability**: V3.2-Speciale reaches gold-medal level at IMO / CMO / ICPC World Finals / IOI 2025
* ✅ **Code and development tasks**: Inherits the strong coding capabilities of the V3 series
* ✅ **Long-context stability**: DSA brings document-length and codebase-level analysis capabilities
* ✅ **Structured tool calling**: Suitable for building multi-step planning and execution agents
***
## DeepSeek Sparse Attention: longer, more efficient
DSA is the core technical upgrade of V3.2, through **lightning indexer + fine-grained token selection** achieves:
* First to implement fine-grained sparse attention on a large model
* Reduces the core attention complexity from O(L²) to
* Significantly speeds up long-context training and inference while maintaining output quality nearly identical to dense attention
| Scenario | Recommended usage | Example |
| --------------------------------- | ----------------------- | ------------------------------------------------------------ |
| Short conversations / simple Q\&A | Direct invocation | Daily Q\&A, summarization |
| Medium-complexity tasks | Enable tool calling | Data analysis, code refactoring |
| Complex agent tasks | Thinking + tool calling | Multi-step planning, codebase analysis, long document review |
***
## Open, usable, ecosystem-friendly
* ⚡ Long-context inference acceleration brought by DSA
* 💰 Through CherryIN in Cherry Studio **Free to use**
* 🖥️ Open-source weights, MIT license, Day-0 support from mainstream inference frameworks such as vLLM and SGLang
***
## Focus on practical capabilities: code and agents
DeepSeek V3.2 performs especially well in real-world development workflows:
* Multilingual code generation and refactoring
* Codebase-level context understanding and patch generation
* Agent toolchain: stable calls to external tools, search, code execution
* Math and complex reasoning: supports competition-level problems
***
## How to use in Cherry Studio?
1. Open Cherry Studio and go to **Settings → Model Services**.
2. Find **CherryIN** service provider and enable it.
3. Select **DeepSeek V3.2**.
4. Return to the chat interface and switch to **DeepSeek V3.2** to start chatting.
> 💡 Tip: The free model quota provided by CherryIN is covered by Cherry Studio official, suitable for daily testing and evaluation; for production environments, it is recommended to use it together with the official DeepSeek API.
***
📘 **Experience DeepSeek V3.2 now and start your flagship reasoning and agent journey!**
***
### Get help and submit feedback
If you encounter any questions, bugs, or have suggestions for feature improvements during configuration or use, please refer to [Feedback and Suggestions](/docs/en-us/question-contact/suggestions.md) for the official channels provided.
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://docs.cherryai.com.cn/docs/en-us/pre-basic/providers/cherryai/free-deepseek.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.